What we want to do
What we’d like to do is to use the methods developed for artificial neural networks, because we know they work really well.
For more
This isn’t going to be a complete or comprehensive guide, so if you haven’t encountered this before, stop now and read an introduction.
So let’s quickly recap how that goes.
First we write the neural network as a function of inputs and parameters.
Where is a vector of parameters, is an input vector, and is an output vector.
We want to minimise some loss function that tells us how far the output of the network is from the desired output .
To do that, we apply gradient descent, moving in the reverse direction of the gradient of the loss function with respect to the parameters.
Where is a learning rate, and we use the chain rule to compute the term.
We can compute the gradient efficiently using vector and matrix multiplies using the vector chain rule.
So, can we just do this for a spiking neural network? It’s not quite so easy. Let’s see why.
Why we can’t do it
To see what goes wrong here, let’s start with a recap of the leaky integrate-and-fire neuron we’ve seen before.
Table 2:Leaky integrate-and-fire neuron definition
Condition | Model behaviour |
|---|---|
Continuous evolution over time | |
On presynaptic spike index | |
Threshold condition, fire a spike if | |
Reset event, after a spike set |
Over time it evolves according to a differential equation, with instantaneous effects when a spike arrives. Whenever the membrane potential crosses the threshold you fire a spike and instantly reset to 0.
We’re going to rewrite these equations, temporarily ignoring the synaptic connections for simplicity. You get the same problem and solution with synapses but it makes the notation more complicated.
The threshold we’ll write as being the Heaviside function of . So this will be equal to 1 if the neuron has spiked, otherwise 0.
Reminder that the Heaviside function is defined as follows:
Now we replace the differential equation with a discrete update rule. To get at time we multiply at time with an exponential term (this comes from just solving the differential equation to get at time with initial condition at time ). We also fold in handling the spike reset by then multiplying this value by . So this means we multiply by 0 if it spiked, otherwise we multiply by 1. This is equivalent to setting it to 0 after a spike.
Now if we wanted to use gradient descent we’d have to compute the gradient using the chain rule. That’s unproblematic for every part of these equations except for the Heaviside function. This function has derivative zero at every point except 0, where it’s undefined.
That means the gradients are zero almost everywhere. Which means that gradient descent will never change any parameters, making it useless for spiking neural networks.
So, how do we solve this problem?
So what can we do?
Well there’s a lot of different approaches that have been tried and that we’ll talk about in the remaining sections this week. There’s no ideal solution, so in this final part of this section we’ll quickly talk about the general approaches people have tried and some of their different issues.
Solution 1: Don’t use gradients (for spiking part)
The first idea is just not to use gradients, or at least, not to use them for the spiking part of the network.
One example of this is reservoir computing. You have a spiking neural network that you don’t train with gradients, and a trainable readout layer.
This actually works surprisingly well, but it’s not an efficient way to learn because you’re not using all the available parameters. 😭
Alternatively you can use global optimisation methods like evolutionary algorithms.
This works but you have to throw a lot of compute at it. 😭
You can try taking an artificial neural network and converting it to a spiking neural network.
Again, this works reasonably well but it doesn’t find solutions that make use of spiking, and so it’s not using the spiking neurons efficiently. 😭
Solution 2: Restrict to a single spike
Another type of solution is to insist that each neuron fires precisely one spike, and take derivatives with respect to the time of that spike,
This gives a nicely differentiable quantity.
This is a clever solution that works surprisingly well in practice. The downside is that it’s unrealistic to assume only one spike per neuron, and that really limits what you can do with it. 😭
Solution 3: Smooth out the spikes
A clever trick is to take the non-differentiable Heaviside function and smooth it out to a sigmoid that you can differentiate.
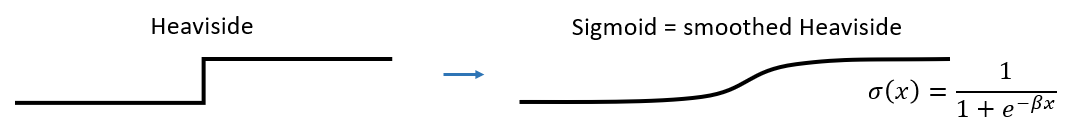
This has been shown to work in at least some cases
However it’s not a spiking neural network if you do that. 😭
A related trick is to look at probabilistic neuron models, and then the parameters of their distributions are differentiable.
This is theoretically nice, but in practice doesn’t seem to scale well. 😭
Solution 4: Surrogate gradients
A more generally applicable approach is a method called surrogate gradients. We’ll talk more about this in a later section. The key idea is we do the same smoothing, but only when we’re computing gradients, not for the the forward pass.
It’s a bit surprising, but this works. We provide gradients to a different function from the one we’re optimising, but it gives us good solutions. We have some ideas of why this works but it’s not a fully rigorous explanation.
This method is still quite computationally expensive, but it is feasible to use it for networks of a few thousand neurons at least. 😑
One downside is that it uses global information that wouldn’t be available to a neuron in a biological setting. This is fine if we just want to know what a good solution would look like, but makes it a bad model for how the brain learns. 😢
Solution 5: Approximate gradients
To address both these issues, people use approximations that reduce the computational complexity and make the learning rules only use local information.
Performance does tend to be worse 😢
But on the upside, these rules are more biologically plausible. 😊